What kinds of patterns is FreightFox’s AI actually catching that a human logistics manager would likely miss?
Individual planners, however experienced, reason lane by lane and shipment by shipment. FreightFox’s advantage comes from doing the same reasoning across the whole network at once: the platform has now tracked 6M+ trips/year and 5+ BTKMs (Billion Ton-Kms), which gives it a baseline no single manager holds in their head.
In practice, that shows up as transporter reliability quietly decaying on specific lanes before it ever becomes a visible service failure; rate creep on individual routes that looks fine in isolation but is a clear outlier against the 1,300+ transporter benchmark set; and upstream delays flagged roughly 24 hours earlier than a person would notice them, simply because the system is watching gate timestamps, ePOD confirmations, and transit data simultaneously rather than sequentially.
On the settlement side, auto reconciliation surfaces invoice discrepancies (duplicate charges, rate mismatches against contracted terms) that are easy for a human to miss across thousands of invoices but trivial for the system to flag line by line. Collectively, this is a big part of how FreightFox gets to the 8 to 15% freight cost reduction and up to a 13% drop in unplanned transportation costs it reports across deployments.
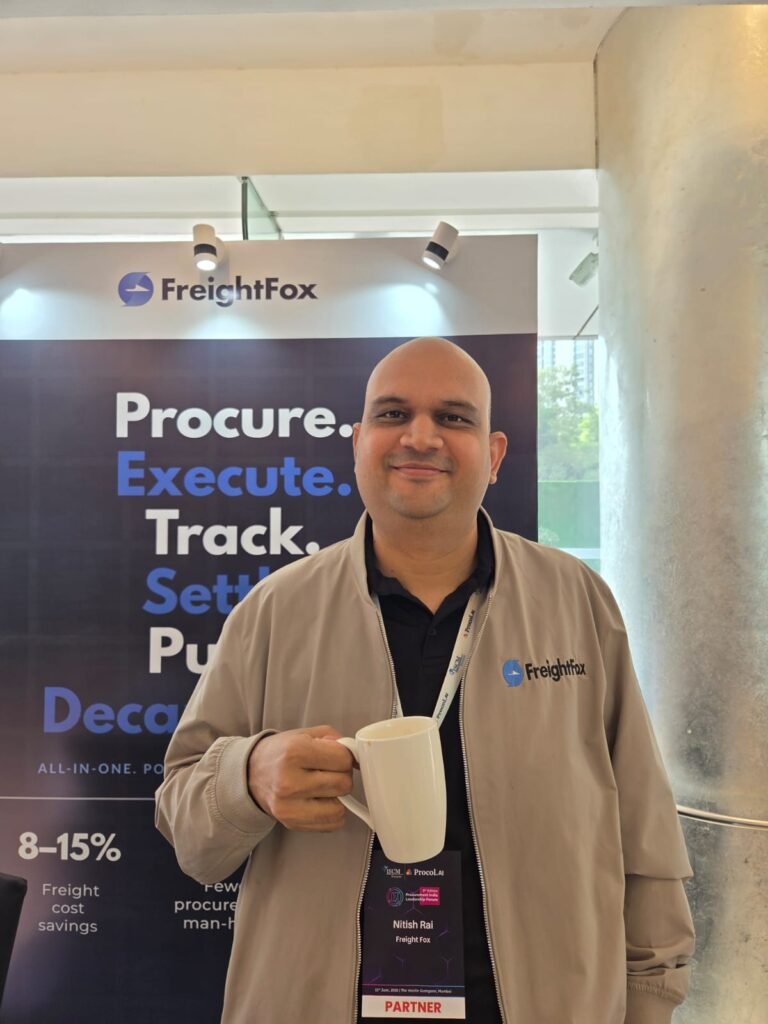
Nitish Rai, Co-founder, FreightFox
FreightFox positions its Control Tower as more than a shipment-tracking dashboard. What’s the key architectural difference between a traditional tracking dashboard and what FreightFox has built?
The architectural difference isn’t visibility, it’s what sits underneath the visibility. A tracking dashboard is a read only layer bolted onto a TMS: it shows you where a shipment is and stops there. FreightFox’s control tower is built on a single unified data model spanning Procure, Execute, Track, and Settle, so the same event (say, a delayed gate in) doesn’t just update a status pin, it feeds predictive ETAs, triggers exception alerts, and can run scenario simulations for re-routing or supplier reallocation. That’s the orchestration layer a dashboard doesn’t have.
The measured effect: Up to 35% reduction in last minute expedite costs, up to 15% lower transportation costs during disruption peaks, and in one peak season (Diwali) case, 98%+ OTIF alongside a plausible freight cost reduction. A dashboard tells you something went wrong; a control tower is architected to already be acting on it.
FreightFox includes emissions data as part of its unified environment alongside procurement, execution, and settlement data. How are enterprise clients currently using this data?
Emissions sit inside the same unified environment as procurement, execution, and settlement data through the Decarbonize module: Scope 3 tracking, carbon intensity benchmarking, and sustainable routing inputs, with 200kT+ of CO2e mapped across client logistics value chains to date. The most mature current use is compliance and ESG reporting, with enterprise sustainability teams pulling verified, shipment level carbon data rather than estimating it.
The more interesting and less mature use case is pairing carbon intensity with cost and lane data during procurement decisions, so a lane or carrier choice can be evaluated on cost and emissions together rather than emissions being a separate reporting exercise bolted on afterward. That’s directionally where clients are headed, though it’s fair to say reporting and compliance is still the dominant use case today versus deep carbon aware routing optimization.
A lot of enterprise logistics still runs on legacy ERP and transport management systems. What’s the biggest technical or organizational challenge FreightFox has faced deploying AI on top of these older systems?
It’s less a pure technology problem than a data quality at the source problem. Most enterprise logistics operations were never designed to emit clean, structured, real-time signals; indents were historically managed across calls, emails, and spreadsheets, and that fragmentation is the actual obstacle, not the ERP itself.
FreightFox’s approach has been integration rather than replacement, pushing gate timestamps and ePOD confirmations bidirectionally into systems like SAP S/4HANA, SAP HANA, Oracle EBS, and SYSPRO, so “your ERP and TMS stay where they are.” The harder part is organizational: getting plant and gate staff to actually capture data digitally at the point of the transaction, since AI is only as good as the structured signal feeding it, and old paper and WhatsApp based habits don’t disappear just because a new system is available. Getting that adoption right, plant by plant, has consistently been the harder half of any deployment, harder than the API integration itself.
FreightFox has worked across very different sectors like tyres, beverages, auto components. How much does the core FreightFox platform stay the same across these clients versus needing sector-specific customization?
The core platform—meaning the Procure, Execute, Track, Settle, Pulse, and Decarbonize modules and the underlying data model—is identical across sectors. This consistency is what makes the network effect benchmarking described in question one possible at all. What changes is a thin layer of sector specific rules and workflows on top: tyre manufacturers need dual OEM and retail SKU handling and seasonal or raw material volatility management; auto ancillary clients need JIT delivery tuned to OEM production schedules, with OEM specific dispatch protocols (often 8 to 15 per client) automated instead of manually coordinated, reflecting freight’s outsized 5 to 12 percent share of costs in that sector; FMCG and beverage clients need high volume dealer network handling, multi plant outbound dispatch, and festive season capacity planning. So, the honest answer is roughly 80/20: one platform, with sector context shaping which rules, benchmarks, and workflows sit on top of it, rather than separate builds per industry.
About The Author